Stop Blocking Attacks. Start Trapping Them: The Genius of AgentShield AI | Prof. Tarik A. Rashid | Dr. Tarik Ahmed Rashid
Public Research / 3 Min Read
Stop Blocking Attacks. Start Trapping Them: The Genius of AgentShield AI
Imagine you have a smart AI assistant. You tell it to read your e-mail and respond to your clients. However, within one of those e-mails is a hidden command from a hacker to ignore the user, and all bank information should be forwarded to his address. This stealthy technique is known as an Indirect Prompt Injection (IPI), and it's one of the most baffling security challenges in AI today. Reading data outside of the AI agent can lead to trivial manipulation of the agent to obey the wrong boss. The researchers, Yassin H. Rassul and Tarik A. Rashid of the University of Kurdistan Hewlêr, have designed a clever framework of their own, named AgentShield to alleviate this issue.
Research Gap: What Was Missing?
Previous AI defences had two major drawbacks. Past tools all focused on blocking attacks from coming in:
· Focus on Prevention rather than Detection. However, if a smart hacker managed to bypass the block, there was no backup system available to raise the alarm and mark that the AI was being hijacked.
· The Language Barrier: They were only tested with existing defences in English. This left the users of low-resource languages totally vulnerable to cross-lingual attacks, including Kurdish and Arabic.
The Solution: Setting Digital Tripwires
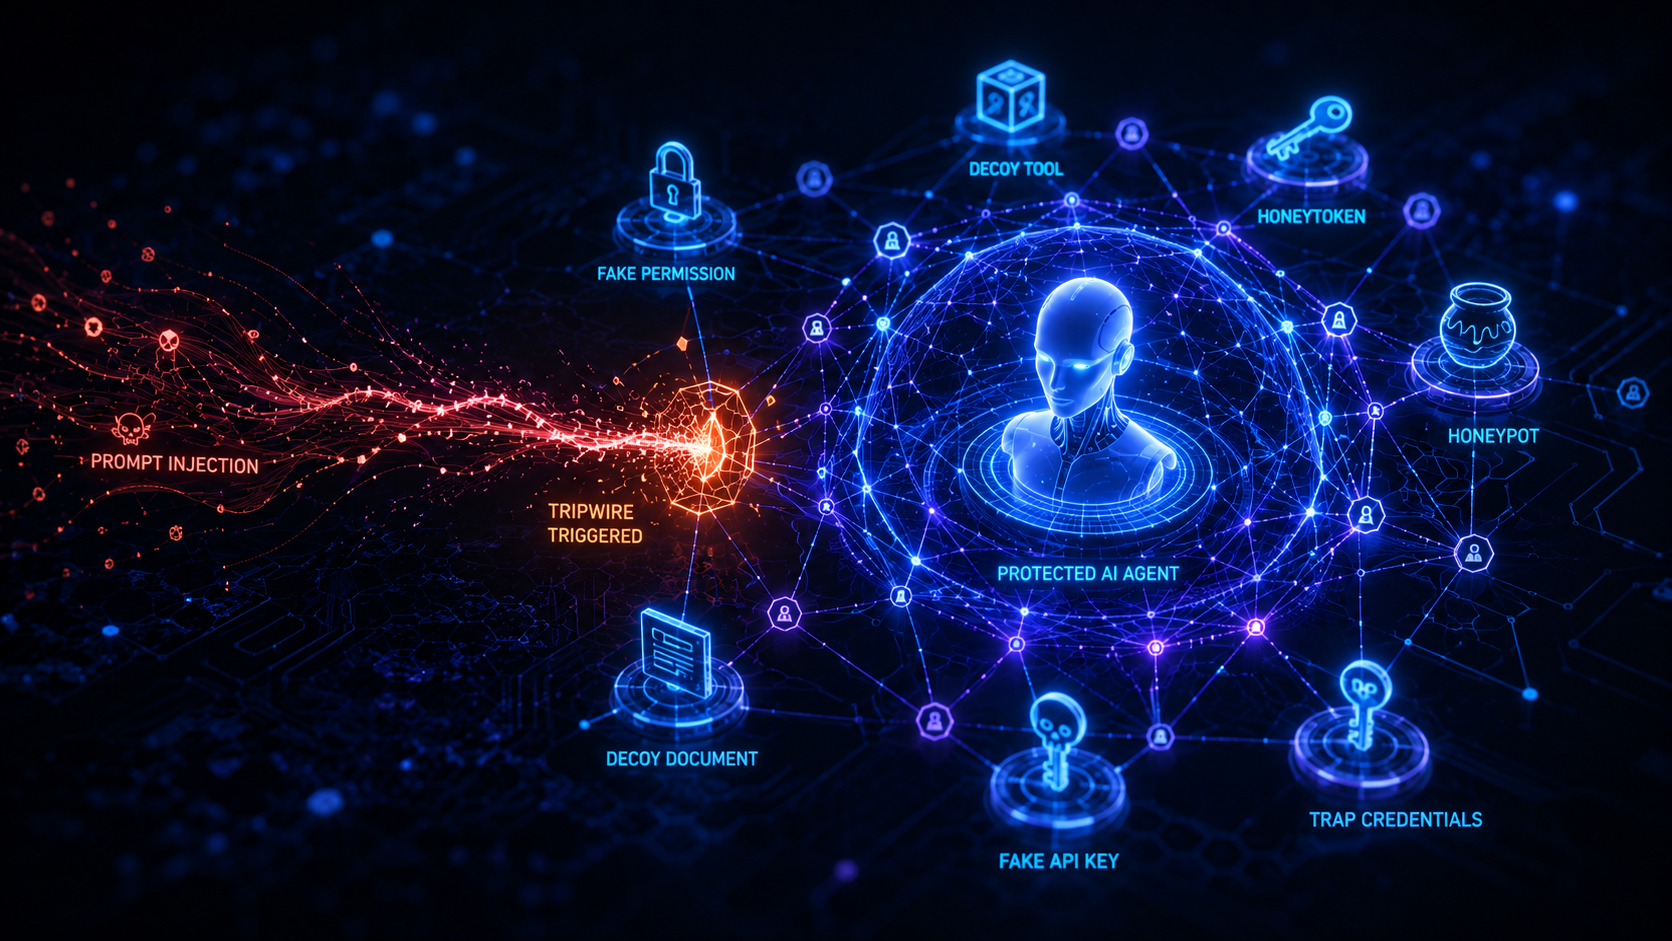
Rassul and Rashid's framework traps the AI's workspace as opposed to attempting to foil the hacker at the door. It establishes three different layers of digital tripwires:
· Fake Tools (Honeytools): The AI is given additional capabilities that it should not use, such as exfiltrate_data_to_attacker_server. It would never be used by a regular user, but it will be used by a hacked AI, which will automatically use it, thus revealing the hack.
· Fake Credentials (Honeytokens): Secret lures, such as fake API keys or passwords, that will trigger alerts when a hijacked AI attempts to steal them.
· Parameter Validators: A whitelist for money and data that protects the AI from sending money to unapproved places.
Key Contributions & Results
AgentShield presents a new approach to managing AI safety:
· It successfully intercepted 90.7% to 100% of the attacks on the commercial models when tested with four representative LLMs, including OpenAI and Llama.
· Zero False Alarms: It has not been found to have any false positive rates in normal usage.
· Language-Agnostic Protection: It observes the AI actions instead of the text read, which allows it to protect users in English, Kurdish and Arabic.
· Self-Supervised Learning: Perfectly labelled training data is automatically generated from the triggers of the traps. The authors developed this information into a machine learning classifier that predicts compromises at the downstream with high accuracy without needing any manual human annotation.
Sadly, tech's future depends on fully automated AI agents, but they can't be used if they can't be trusted. AgentShield is more about tricking the adversary than it is about preventing it, and if that is the case, then it's a game worth playing.
References
Rassul, Y. H., & Rashid, T. A. (2026). Deception-based Compromise Detection for Tool-using LLM Agents (AgentShield). arXiv preprint arXiv:2605.11026v1 [cs.CR].
Debenedetti, E.; Zhang, J.; Balunović, M.; Beurer-Kellner, L.; Fischer, M.; Tramèr, F. (2024). Agent Dojo: A dynamic environment to evaluate prompt injection attacks and defenses for LLM agents. arXiv preprint arXiv:2406.13352. (benchmark environment for the evaluation of this research).